
Common Issues
This page covers the most common ChannelWatch failures and the fastest path to the right fix without touching source code.
How to use this page
Section titled “How to use this page”Start with the symptom you can confirm right now:
- If the container is stopped, crashing, or the web UI never loads, go to Container won’t start.
- If the container is running but an expected alert never arrived, start with Alert didn’t fire.
- If notifications are arriving but look wrong, duplicated, or incomplete, use Diagnostics for guided tests or CLI Commands for headless checks.
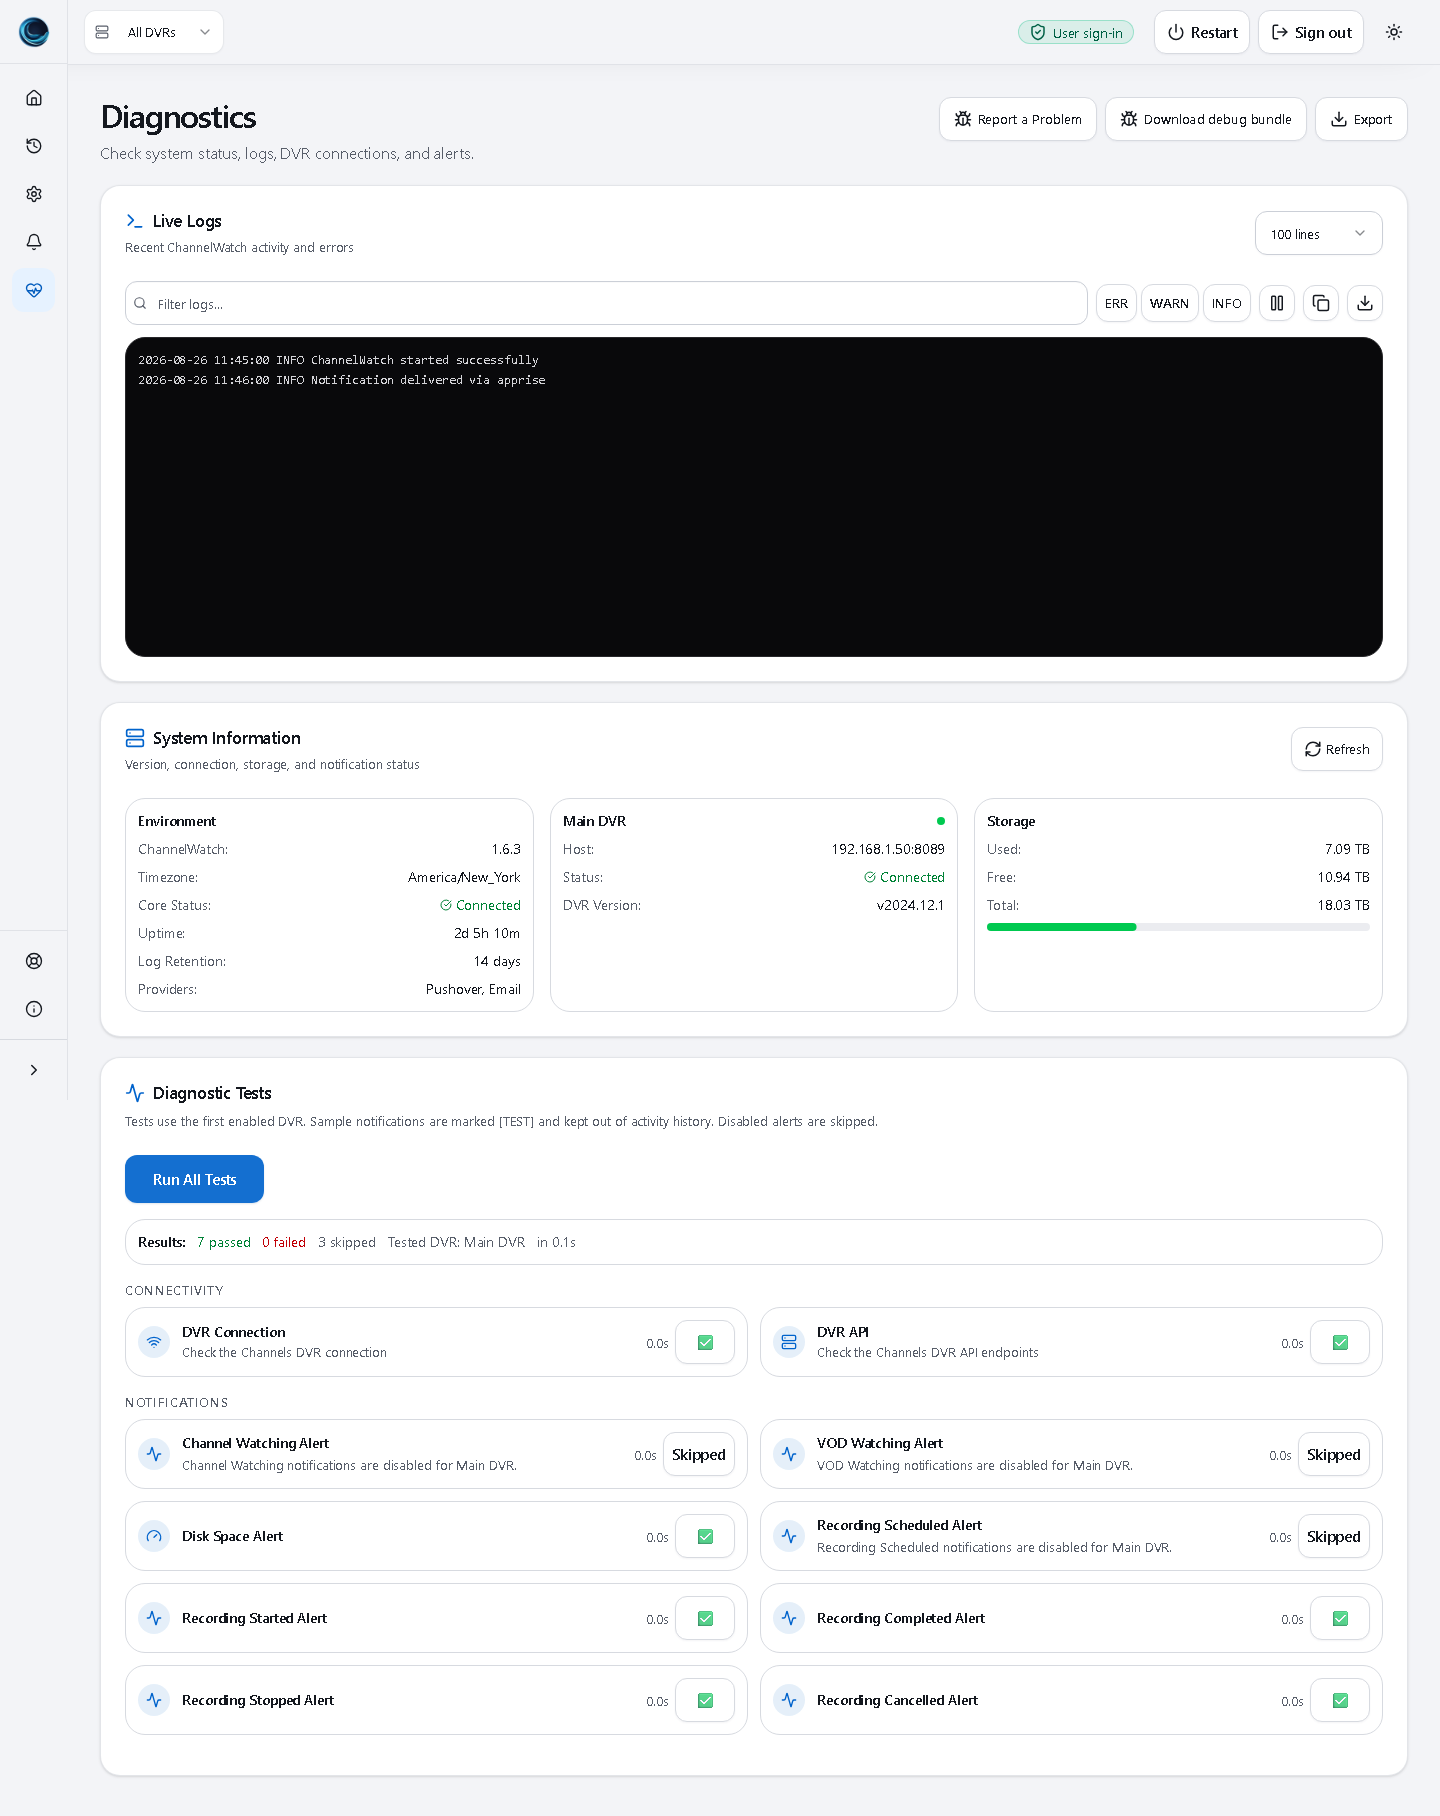
- If you need to send a support report, use Report a Problem from Diagnostics so the app can prepare a sanitized preview and validate screenshots or a debug bundle.
Alert didn’t fire
Section titled “Alert didn’t fire”Notifications are silent when any link in the chain breaks: the container, the DVR connection, the provider credentials, or the alert configuration. Work through these steps in order.
1. Check the container logs
Section titled “1. Check the container logs”docker logs channelwatchLook for lines marked ERROR or WARNING. Common messages include connection refused (DVR unreachable), authentication errors (bad provider credentials), and startup failures. If the log is empty or the container is not running, see Container won’t start below.
2. Verify DVR connectivity
Section titled “2. Verify DVR connectivity”Open Diagnostics > Diagnostic Tests > Connectivity and run DVR Connection. In v1.6.0, an Unknown test name received result is a known test-label mismatch; use --test-connectivity from CLI Commands instead. A real connection failure can indicate an unreachable DVR, incorrect address, or firewall rule.
If you’re using bridge networking instead of host networking, confirm that the DVR host is reachable from inside the container. The DVR address must be the host machine’s LAN IP, not localhost or 127.0.0.1.
3. Check provider credentials
Section titled “3. Check provider credentials”Go to Settings > Notifications and confirm the provider is enabled and its credentials are correct. Pushover requires a User Key and an API Token. Other providers use the fields described on their setup page; use a service URL in the Custom Apprise provider.
Send one sample alert using Diagnostics or the matching CLI command. This sends a real notification. Read the sender result and logs, then confirm receipt at the destination. An unknown-test-name error needs the CLI fallback before drawing conclusions about credentials or delivery.
4. Confirm alerts are enabled
Section titled “4. Confirm alerts are enabled”Go to Settings > Alerts and verify that the alert type you expect is toggled on. A provider can be configured correctly but produce no notifications if the corresponding alert type is disabled.
5. Check for a startup grace period (disk alerts only)
Section titled “5. Check for a startup grace period (disk alerts only)”Disk space alerts have a startup grace period (default 10 seconds) during which no alerts fire, even if free space is already below a threshold. If you restarted the container and expected an immediate disk alert, wait for the grace period to pass and check again.
Notification flood on reconnect
Section titled “Notification flood on reconnect”Symptom: Many notifications arrive in a burst immediately after the container restarts or after the DVR server reconnects.
ChannelWatch re-establishes its DVR event stream after a restart. It uses saved per-DVR session state to recognize existing viewers. Missing, unwritable, or incompatible state can make an existing session appear new.
Keep the same writable /config volume across updates and restarts. Check the logs for session-state load or save failures, and verify that the DVR still has the same saved ID. Do not delete session-state files as a first troubleshooting step.
If the problem repeats, record the restart time, affected DVR, and relevant redacted log lines. A release number alone does not prove that reconnect state loaded successfully. See FAQ for the persistence behavior.
Provider failed
Section titled “Provider failed”Symptom: A test alert in the Diagnostics tab fails with an authentication error or network error.
Fix: Re-enter the provider credentials in Settings > Notifications, then send the test again. If the error changes from authentication to delivery, the saved credentials were the problem.
If the UI reports a network error, confirm the container has outbound internet access and check the provider’s status page for an outage. For provider-specific setup details, go back to the matching page under the Notifications section.
If provider tests keep failing while DVR tests pass, the problem is the notification path, not the DVR connection.
DVR disconnected
Section titled “DVR disconnected”Symptom: The dashboard shows a disconnected DVR or a connectivity check fails.
Fix: Verify the DVR host and port in Settings > General > DVR Servers first. If you’re using bridge networking, the DVR address must be the host machine’s LAN IP, not localhost or 127.0.0.1.
Then run the connection check again from Diagnostics. Use channelwatch doctor diagnose for a sweep of configured DVRs or --test-connectivity for the first enabled DVR. See doctor CLI and CLI Commands for the commands. Investigate a confirmed connection failure before changing provider credentials.
Container won’t start
Section titled “Container won’t start”If docker compose up -d completes but the container exits immediately, or if the web UI is unreachable, check the following.
Port conflict
Section titled “Port conflict”ChannelWatch uses port 8501 for the web UI. If another process on the host is already using that port, the container will fail to bind and exit.
Check what’s using the port:
ss -tlnp | grep 8501If something else is using 8501, either stop that process or change ChannelWatch’s port. With bridge networking, map a different host port:
ports: - "8502:8501"With host networking, there is no port mapping option. You would need to stop the conflicting process or switch to bridge mode.
Volume permission error
Section titled “Volume permission error”ChannelWatch writes configuration and logs to the /config volume. If the host directory is owned by root and the container process cannot write to it, the container will exit with a permission error.
Check the logs:
docker logs channelwatchIf you see Permission denied errors referencing /config, check the PUID and PGID configured for this container. Correct ownership only on the directory mapped to /config. For a deployment using UID and GID 1000, the command is:
sudo chown -R 1000:1000 /your/local/pathReplace /your/local/path with that exact host directory, and replace 1000:1000 with your configured IDs when they differ. Unraid commonly uses different IDs. Do not run this against a parent directory containing other applications’ data.
Missing or malformed compose file
Section titled “Missing or malformed compose file”If the compose file has a syntax error, Docker will refuse to start the container. Validate it:
docker compose configThis prints the resolved configuration. Any YAML syntax errors appear as parse failures before the output.
Compare the resolved file with the current Docker example. Keep your existing /config mapping and local network choices when correcting syntax.
Disk space alerts spamming
Section titled “Disk space alerts spamming”Symptom: You’re receiving repeated disk space alerts even though your free space hasn’t changed significantly.
ChannelWatch has built-in cooldown and worsening logic to prevent alert fatigue. If alerts are still repeating, one of these settings may need adjustment.
How the cooldown works
Section titled “How the cooldown works”Once a warning or critical alert fires, ChannelWatch will not send another alert at the same severity unless both conditions are met:
- Free space has dropped by at least 1 GB or 1 percentage point since the last alert at that severity.
- The cooldown period has elapsed (default: 1 hour).
If you’re seeing repeated alerts, the cooldown may be set too low, or free space may be fluctuating enough to cross the worsening threshold repeatedly.
Adjusting the settings
Section titled “Adjusting the settings”Go to Settings > Advanced > Disk Alert Controls to adjust:
- Cooldown period - increase this to reduce how often repeat alerts fire at the same severity.
- Worsening sensitivity - increase the minimum GB or percent drop required before a repeat alert fires.
- Warning and critical thresholds - choose limits that reflect the free-space reserve you need. Check whether the rule uses free GB or free percent before changing it; a higher free-space threshold can trigger an alert sooner.
Startup alert on every restart
Section titled “Startup alert on every restart”If you receive a disk alert every time the container restarts, the startup grace period may be too short. Increase it in Settings > Advanced > Disk Alert Controls under Startup grace period.
The grace period delays the first disk check after startup. Raising it to 30 or 60 seconds gives the container time to fully initialize before evaluating disk space.
Related pages
Section titled “Related pages”- Diagnostics - use the web UI diagnostic tools to test connectivity and alert delivery
- Report a Problem - send a sanitized support report with optional private attachments
- CLI Commands - command-line alternatives for headless troubleshooting
- Disk Space - full reference for disk alert thresholds and cooldown logic